A week on Sonnet 5.5: what my agent numbers show
I moved most of my agent work from Opus 5.5 to Sonnet 5.5. Success stayed near 78 percent, rework fell, and blocked doubled. The usage charts, and why reworks mostly need a person, not a fix.
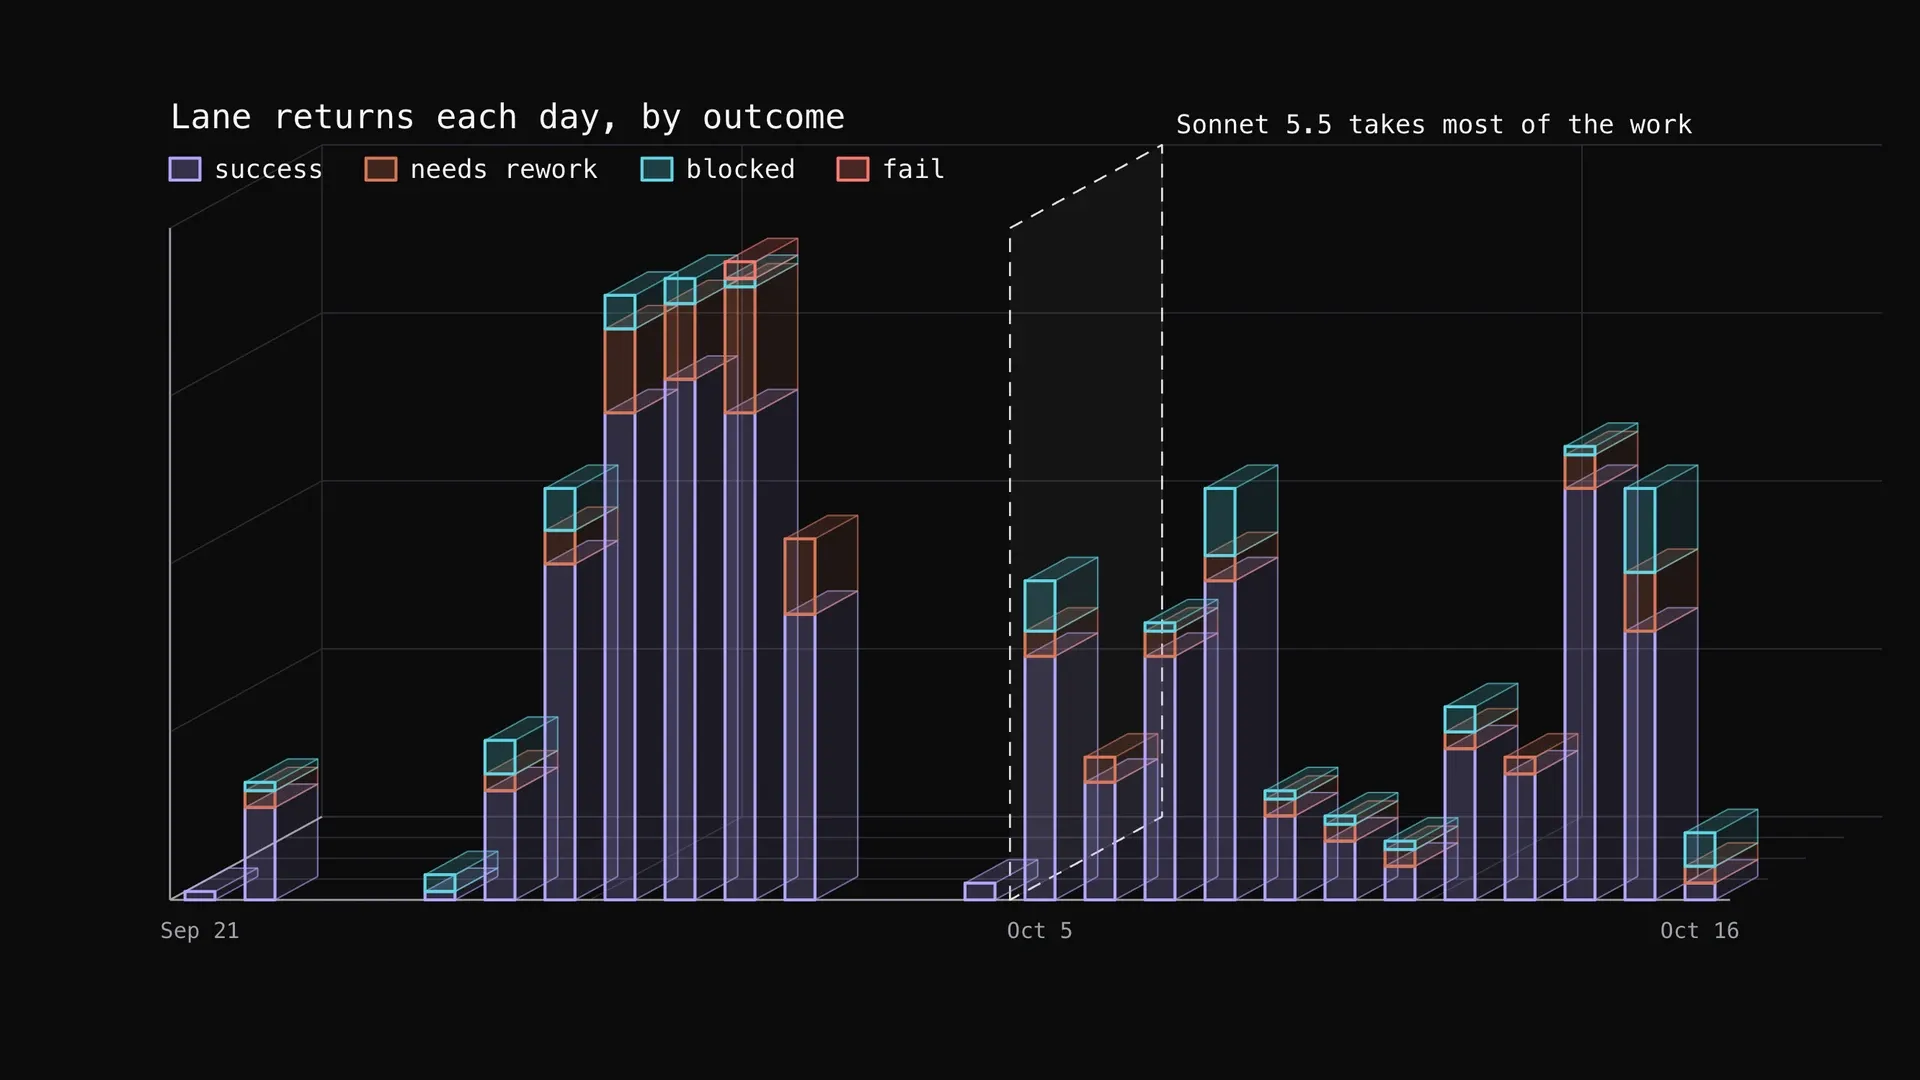
I moved most of my agent work from Opus 5.5 to Sonnet 5.5, and the success share held at 77.7 percent against 79.3 before. Needs rework fell, blocked doubled, and almost no rework came from bad code.
1. What I counted
A lane is one delegated agent task. Each time a lane stops it returns one outcome: success, needs rework, blocked or fail. These are returns, not lanes, so a lane that is blocked and then succeeds counts twice.
Here is what each outcome means in this post. Success: the lane’s criteria were met and the work shipped. Needs rework: the work was wrong, or a named deliverable was missing. Blocked: a person or an outside step is needed before it can finish. Fail: no criterion was met. These are my own working definitions, so read them as how I use the words in this post, not as a standard meaning.
If you run agents of your own, the same four outcomes probably apply to you. Mine added up to 671 returns over the whole window: 527 successes, 86 reworks, 56 blocked and 2 fails.
- Success527
- Needs rework86
- Blocked56
- Fail2
2. The work moved to Sonnet
Sonnet 5.5 went from 0.1 percent of model usage before 2026-10-05 to 66.1 percent after, and Opus 5.5 fell from 98.5 to 32.4 percent. Usage is shown as an index, where 100 is the busiest day.
The empty stretches are days with no recorded usage, so the two windows below hold different numbers of busy days.
Before 2026-09-21 to 2026-10-04
Opus 5.5 98.5%Sonnet 5.5 0.1%Haiku 1.4%Other 0.0%
Sonnet window 2026-10-05 to 2026-10-16
Opus 5.5 32.4%Sonnet 5.5 66.1%Haiku 1.2%Other 0.3%
3. Quality held, the mix changed
The two windows are different lengths, so I compare them by share. Before runs from 2026-09-21 to 2026-10-04 and the Sonnet window from 2026-10-05 to 2026-10-16.
| Outcome | Before (353) | Sonnet window (318) |
|---|---|---|
| Success | 280, 79.3% | 247, 77.7% |
| Needs rework | 51, 14.4% | 35, 11.0% |
| Blocked | 20, 5.7% | 36, 11.3% |
| Fail | 2, 0.6% | 0, 0.0% |
Success slipped by 1.6 points, which is probably inside what two short windows can swing. Rework dropped by 3.4 points. Blocked went from 20 to 36 returns while the total fell, so its share roughly doubled.
Success
Before79.3%
Sonnet window77.7%
Needs rework
Before14.4%
Sonnet window11.0%
Blocked
Before5.7%
Sonnet window11.3%
Fail
Before0.6%
Sonnet window0.0%
Neither model wins this comparison. Two windows and one workload give a direction, and you should not read them as a test.
4. Why a rework happens
I read all 86 needs-rework returns and grouped each by the first open item it names. The grouping is mine and may be wrong in places, so treat it as a rough read.
- No open item24
- Landing or channel action18
- Hook or ownership gate16
- Run still going9
- Human-only step or decision8
- Another owner pending7
- Real defect4
Strictly human-only steps, such as a sign-in or a choice only I can make, were 8 of 86. Add landing work left to a channel and another owner still pending, and 33 wait on a person or on someone else’s step. Only 4 were real defects.
The shift between windows is telling. Hook and ownership refusals fell from 15 of 51 reworks to 1 of 35. The Sonnet window has fewer reworks that hit a process wall, and more that name no open item at all.
5. What it costs me
The price of the shift is handholding. A blocked lane waits for me, and there are more of them. If your own work is mostly a person or a decision away from done, then more blocked returns may simply be the visible cost of running more agents, and you could read them as a sign of capacity in use instead of worse code. That is my guess, not a measured result.
Verdict
On this workload, Sonnet 5.5 did two thirds of the work at the same success share, with fewer reworks and more blocked lanes. The extra usage is worth the handholding to me right now.
Try Sonnet 5.5 on one task: open Claude Code
Responses
Keep reading
How to pace your Claude subscription to survive the week
My Claude weekly limit ran out on day 3 one week and lasted all seven days the next. What changed: a simple wait rule for the strongest model, and the cheaper model doing more of the work, with the real usage charts.
Claude Code usage limits: what burns your quota and how to stretch it
What the Claude Code five-hour and weekly limits are, how they show up, what spends them fastest (long context, large tool output, parallel agents, model choice, retries) and the documented ways to stretch them, with one measured plan week.
Evaluating local models on one 12 GB GPU
Five local models tested on one RTX 4070 (12 GB) with LM Studio and llama.cpp: Qwen3-VL-8B, Gemma 4 12B QAT, Gemma 4 26B A4B, Qwen3.8-27B and Qwen3.6-35B-A3B.