Weekly usage projection: a backtest on 1,540 readings
A weekly usage projection backtested on 1,540 readings: error falls from 8.56 points at 12 h to 1.36 at 2 h, and the alarm uses the lower of two.
A weekly usage projection is only trustworthy near the end of the week. Backtested on 1,540 weekly readings covering 285 h, the smoothed version missed by 8.56 points on average 12 hours before reset and by 1.36 points at 2 hours. The alarm acts on the lower of two projections, so a short burst alone does not trigger it.
How the projection is built
The projection adds expected future burn to the percent already used. The burn rate starts at the smoothed current rate and decays toward the usual rate of that hour with a time constant of 3 h, so a burst fades instead of running to the reset forever.
projection = used + integral of max(rate, 0) over the hours leftalarm projection = lower of (1 h-rate projection, 3 h-rate projection)The warn needs the alarm projection over 100 % at reset, sustained 20 min with 1 h and 3 h agreeing. Raw 1 h momentum is shown beside it and never alarms. On one live reading, 78 percent used with 20.89 h left, the two views split sharply:
| view | projected used at reset |
|---|---|
| raw 1 h momentum | 127.5 % |
| smoothed | 102.3 % |
| 1 h-rate | 101.9 % |
| 3 h-rate | 102.3 % |
| alarm (lower) | 101.9 % |
That is one reading, so it shows the guard working but proves nothing about accuracy.
Error by horizon
Each hour of the stored window was projected forward and compared with the reading at the reset. Errors are in points.
| horizon | n | smoothed | raw 1 h momentum | smoothed bias | p90 | max |
|---|---|---|---|---|---|---|
| T-12 h | 112 | 8.56 | 10.03 | +7.71 | 16.9 | 31.8 |
| T-6 h | 110 | 3.54 | 4.04 | +2.14 | 8.1 | 17.2 |
| T-2 h | 133 | 1.36 | 1.49 | +0.38 | 2.8 | 5.2 |
The smoothed projection beats raw momentum at every horizon, though only narrowly at 2 hours. It runs biased high at long horizons, so it tends to warn early rather than miss a run-out. If the week is already tight, the pacing rules matter more than any early alarm.
What two resets can and cannot show
Only two resets have completed in the store, so the table below is thin evidence.
| reset | T-12 h | T-6 h | T-2 h | actual |
|---|---|---|---|---|
| first | 117.3 % (+17.3) | 107.6 % (+7.6) | 102.8 % (+2.8) | 100.0 % |
| second | 146.5 % (+90.5) | 146.5 % (+90.5) | 59.4 % (+3.4) | 56.0 % |
The second row ended far below its early projections, so it is read as an outlier, not as evidence for or against the model. For what spends the quota in the first place, see Claude Code usage limits.
Verdict
Trust a weekly usage projection inside the last half day, where the error was 1.36 points, and treat earlier warnings as a nudge. Using the lower of two projections keeps raw momentum from raising the alarm on its own. Two completed resets is a small sample, so check any projection against your own meter.
Try it on your own plan: read how to pace your Claude subscription
Sources:finding.md, evidence/pace-week/snapshot.json.
Responses
Keep reading
Claude Code usage limits: what burns your quota and how to stretch it
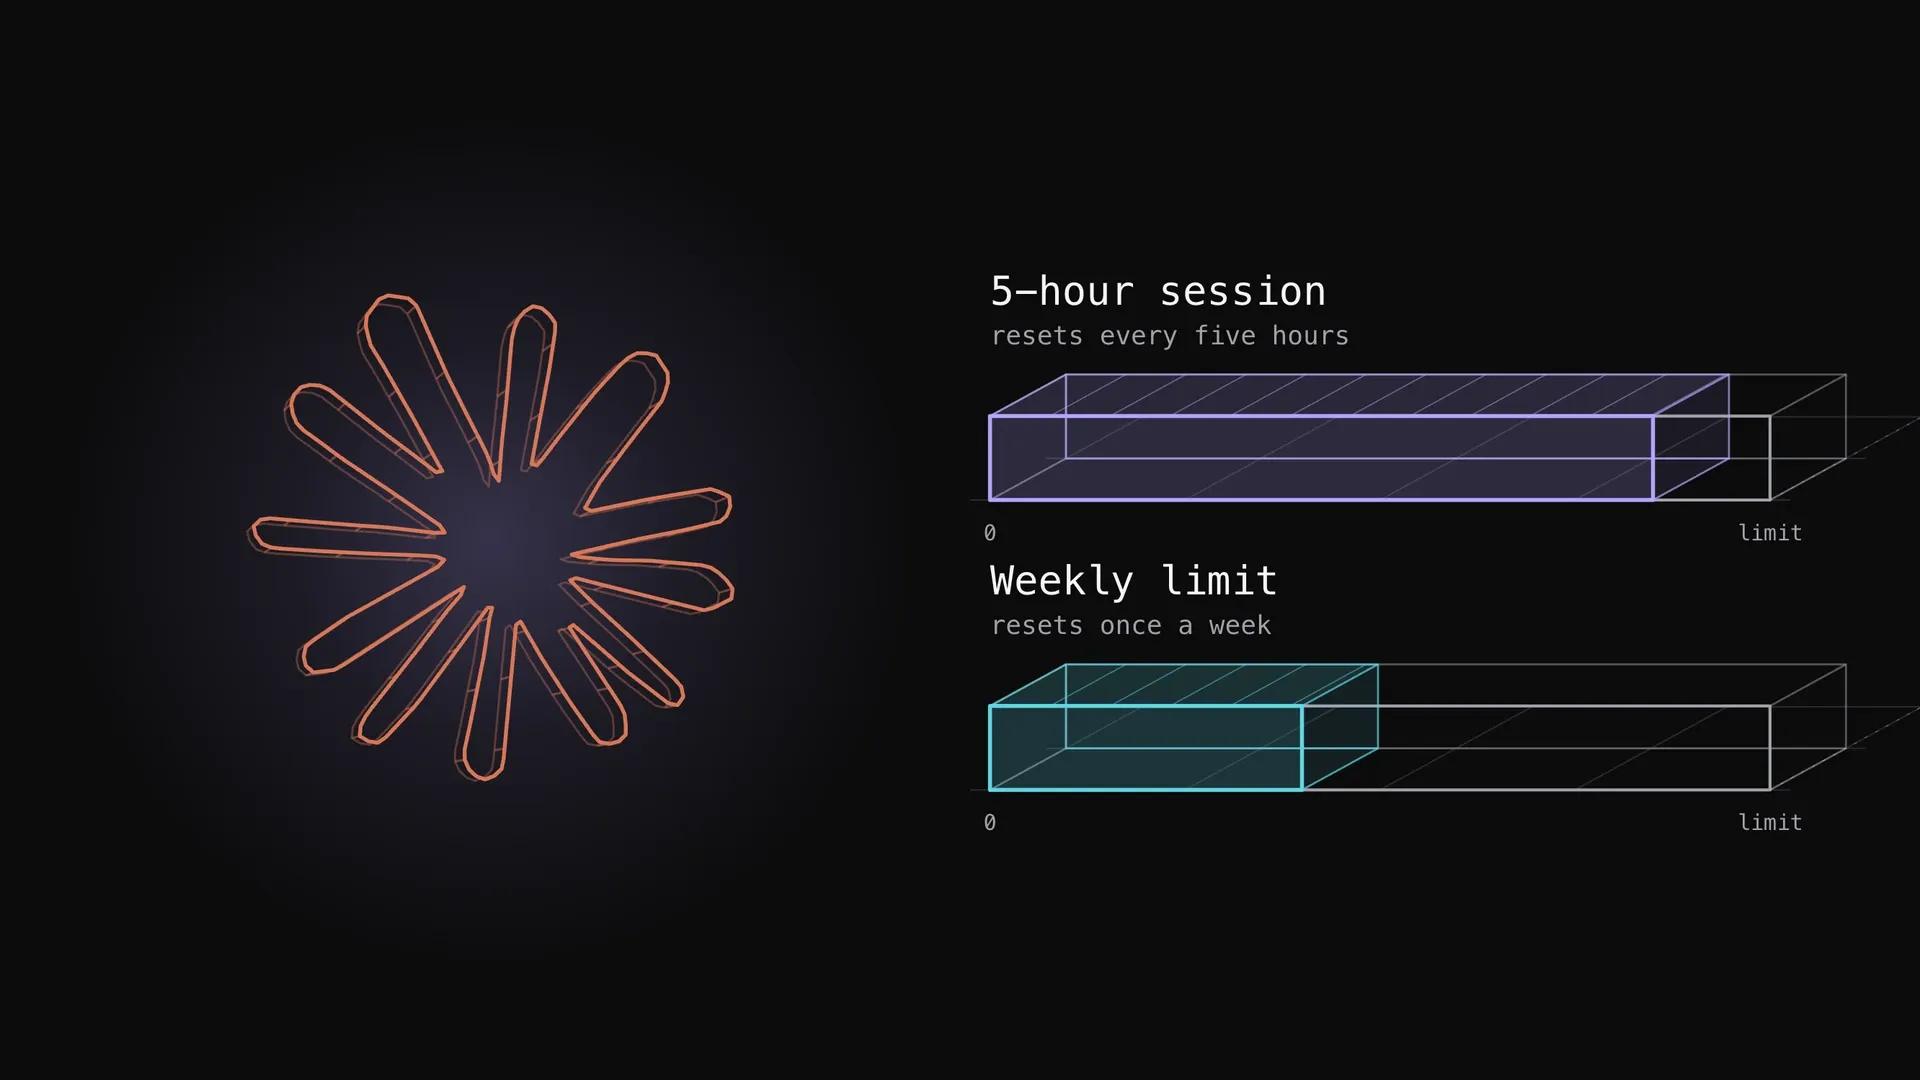
What the Claude Code five-hour and weekly limits are, how they show up, what spends them fastest (long context, large tool output, parallel agents, model choice, retries) and the documented ways to stretch them, with one measured plan week.
Claude model training data: what the help article says
Anthropic's help article says commercial inputs are not used for training by default, but feedback can be. Here is what to check in Claude Code.
Generative UI agent instructions: 2,326 vs 12,720 tokens
Generative UI needs instructions that teach an agent to build cards. A short block cost 2326 tokens, a full guide 12,720, so keep the short block.